This is one of the most common questions in SEO, and also one of the most misunderstood. When a website is not showing on Google, the issue is not always a “lack of SEO.” Before a page can appear in search results, Google needs to discover it, crawl it, index it, and only then decide whether to serve it for a given search. Google also makes it clear that it does not guarantee that it will crawl, index, or serve a page, even if it follows its guidelines.
In practice, that means a site may fail to appear for very different reasons. Sometimes the page is simply too new. In other cases, Google cannot access the content properly, runs into a technical block, chooses a different duplicate version as primary, or simply has not discovered that URL properly yet. That is why finding the right issue matters more than making random SEO changes without diagnosis.
It may simply be too early
If the page or website is new, there may not have been enough time yet. Google recommends waiting at least a week after submitting a sitemap or requesting indexing before assuming there is a problem, and it also explains that recrawling can take from a few days to a few weeks. Requesting indexing does not mean the page will instantly appear in search results.
Google may not be able to access or process the page
For a page to be eligible for indexing, Google lists three minimum technical requirements: Googlebot must not be blocked, the page must return HTTPS 200, and it must contain indexable content. If the URL is blocked, returns an error, redirects badly, or does not expose enough content to be processed, it is normal for it not to appear on Google.
This can also happen more often on JavaScript-heavy sites. Google explains that JavaScript pages go through crawling, rendering, and indexing phases, and that content is not always available in the initial HTML. If important content only loads after user actions, or if lazy loading is implemented incorrectly, parts of the page may remain hidden from Google.
The page may be blocked without you realizing it
A very common reason is the presence of noindex or another signal that prevents Google from treating the page as indexable. Google explains that noindex can be implemented via a meta tag or HTTP header, and that this prevents the page from appearing in search. It also notes that many CMS platforms allow these settings to be changed without directly editing the code.
Also, if the page sits behind a login or password protection, that will prevent normal visibility in Google Search. Google’s documentation explicitly states that protected content of this type will not appear in Search.
Google may be choosing a different version of the page
Sometimes the issue is not that the page does not exist. It is that Google considers another version to be the main one. This can happen with duplicate URLs, parameters, versions with and without a trailing slash, HTTP vs HTTPS, www vs non-www, or very similar pages. Google explains that when no clear preference is provided, it tries to choose the canonical version it considers best, and recommends signals such as rel="canonical", redirects, and sitemaps to guide that decision.
So in some cases, the page may be indexed, just not in the exact version you are looking for. In the indexing report, Google itself reminds site owners that duplicate URLs should not be indexed as separate pages and that important pages should be checked individually.
Google may not be discovering the page properly
Google uses links to find new pages and better understand the relevance and relationship between content. If a page is isolated, weakly linked internally, or depends on elements that are hard to crawl, it may take longer to be discovered. Google recommends crawlable links and a clear internal structure to improve that process.
On sites with infinite scroll, weak pagination, or less clear technical setups, this can also make indexing harder. Google recommends persistent URLs, crawlable pagination, and technical implementations that allow the crawler to find the different content chunks.
There may also be manual actions or security issues
In some cases, the issue is neither technical nor editorial. There may be a manual action or a security issue. Google’s documentation states that if a site has a manual action, some or all of it may not be shown in Search. The Security Issues documentation also explains that certain problems can cause pages or sites to be omitted from results.
How to diagnose it without guessing
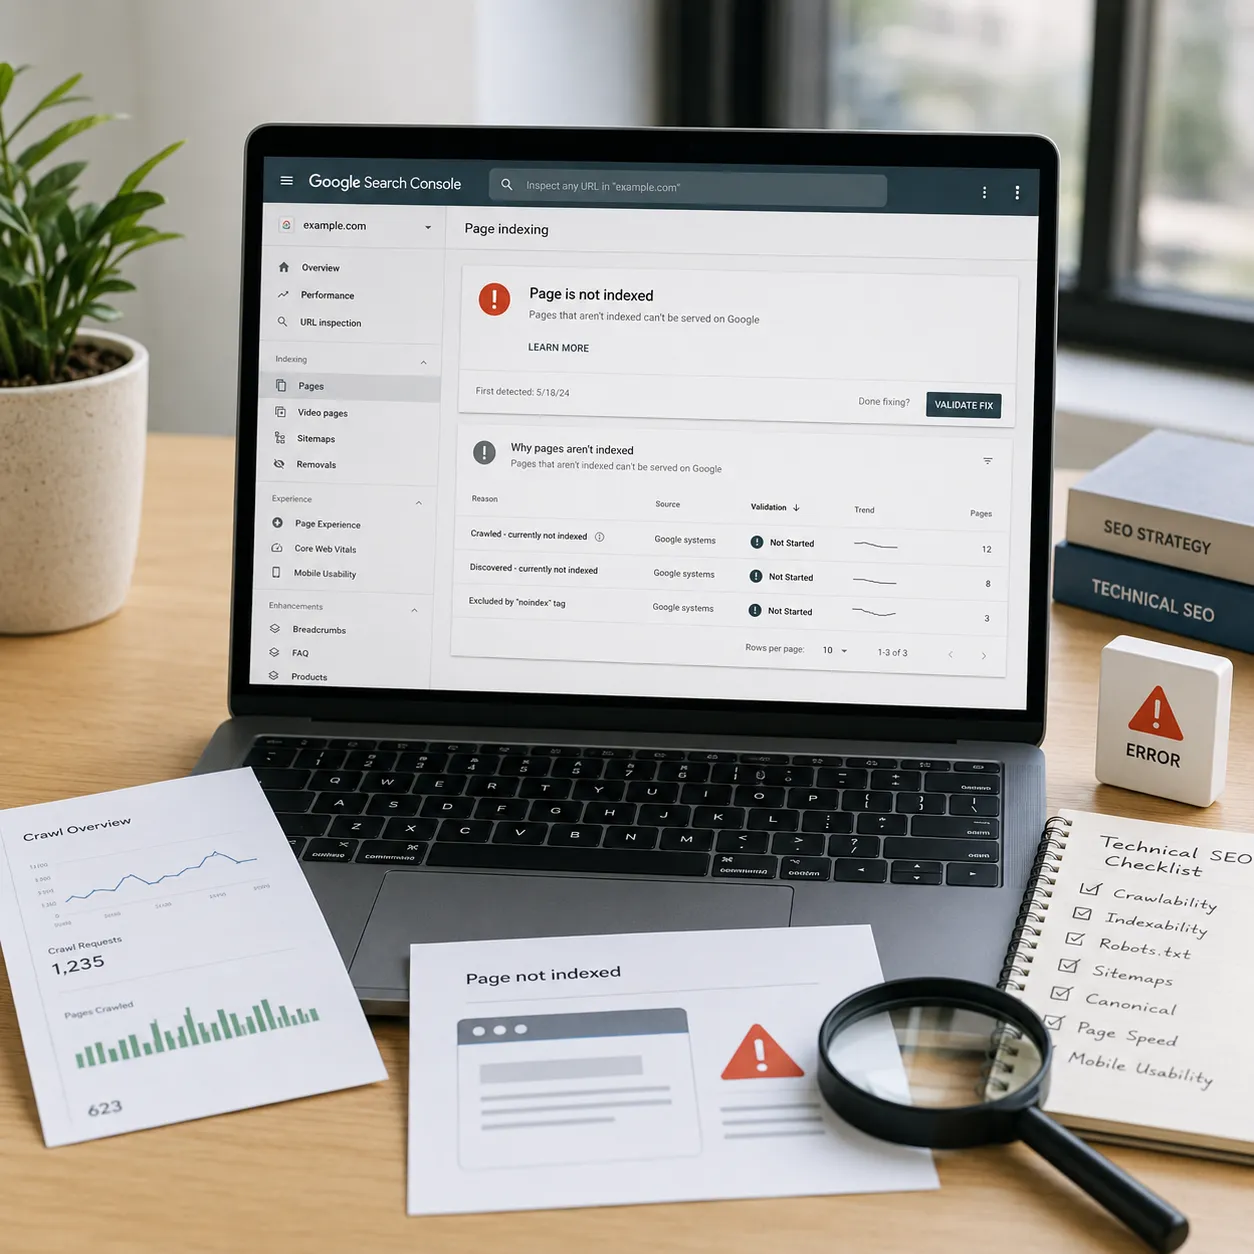
The best place to start is not the site: operator in Google. Google itself says that search operators are limited by indexing and retrieval constraints, and that the URL Inspection Tool in Search Console is more reliable for debugging. It shows whether the URL is indexed, whether it may be indexable in a live test, lets you request indexing, and helps explain why the page may or may not be in the index.
If you want a more useful check, start with:
• **URL Inspection Tool
**• **Page Indexing Report
**• **Manual Actions Report
**• Security Issues Report.
These are the areas most likely to give you concrete signals about what is actually blocking visibility.
Conclusion
If your website is not showing on Google, the issue may be timing, technical blocks, conflicting signals, duplication, weak discovery, or even manual actions and security problems. The most important thing is not to assume straight away that “SEO is not working.” Before that, it is worth checking whether the page is truly accessible, indexable, and being interpreted correctly by Google.